

Stop Asking It to Judge: Use the LLM to Read, Score in Code
Use the LLM only to copy out résumé facts and score them in code. For nine of eleven models the score stopped moving on demographic edits.
Bogdan is a senior engineer who has spent more than 15 years building software, developer tools and open-source projects. At re:cinq, he works hands-on with agentic coding, AI agents and MCP, building and testing new ways of developing software with AI. His recent work includes research into AI hiring bias and tools for autonomously tackling legacy codebases.
7 Articles • Research • AI • Engineering
Use the LLM only to copy out résumé facts and score them in code. For nine of eleven models the score stopped moving on demographic edits.
Three Reddit objections to our hiring-bias study, run as experiments. A placebo control showed a blank line moves the score as much as a school does.
Anthropic's most capable model lands mid-pack on résumé-screening bias. Frontier capability neither fixes nor worsens silent hiring bias.
An audit of 25,500 LLM resume evaluations across ten models tied nearly half the score differences to demographic bias, not work experience.
How I trained a custom diffusion model on 100,000 photos with one Intel Arc B580 in nine days, for 21 euros of power, no cloud GPUs.
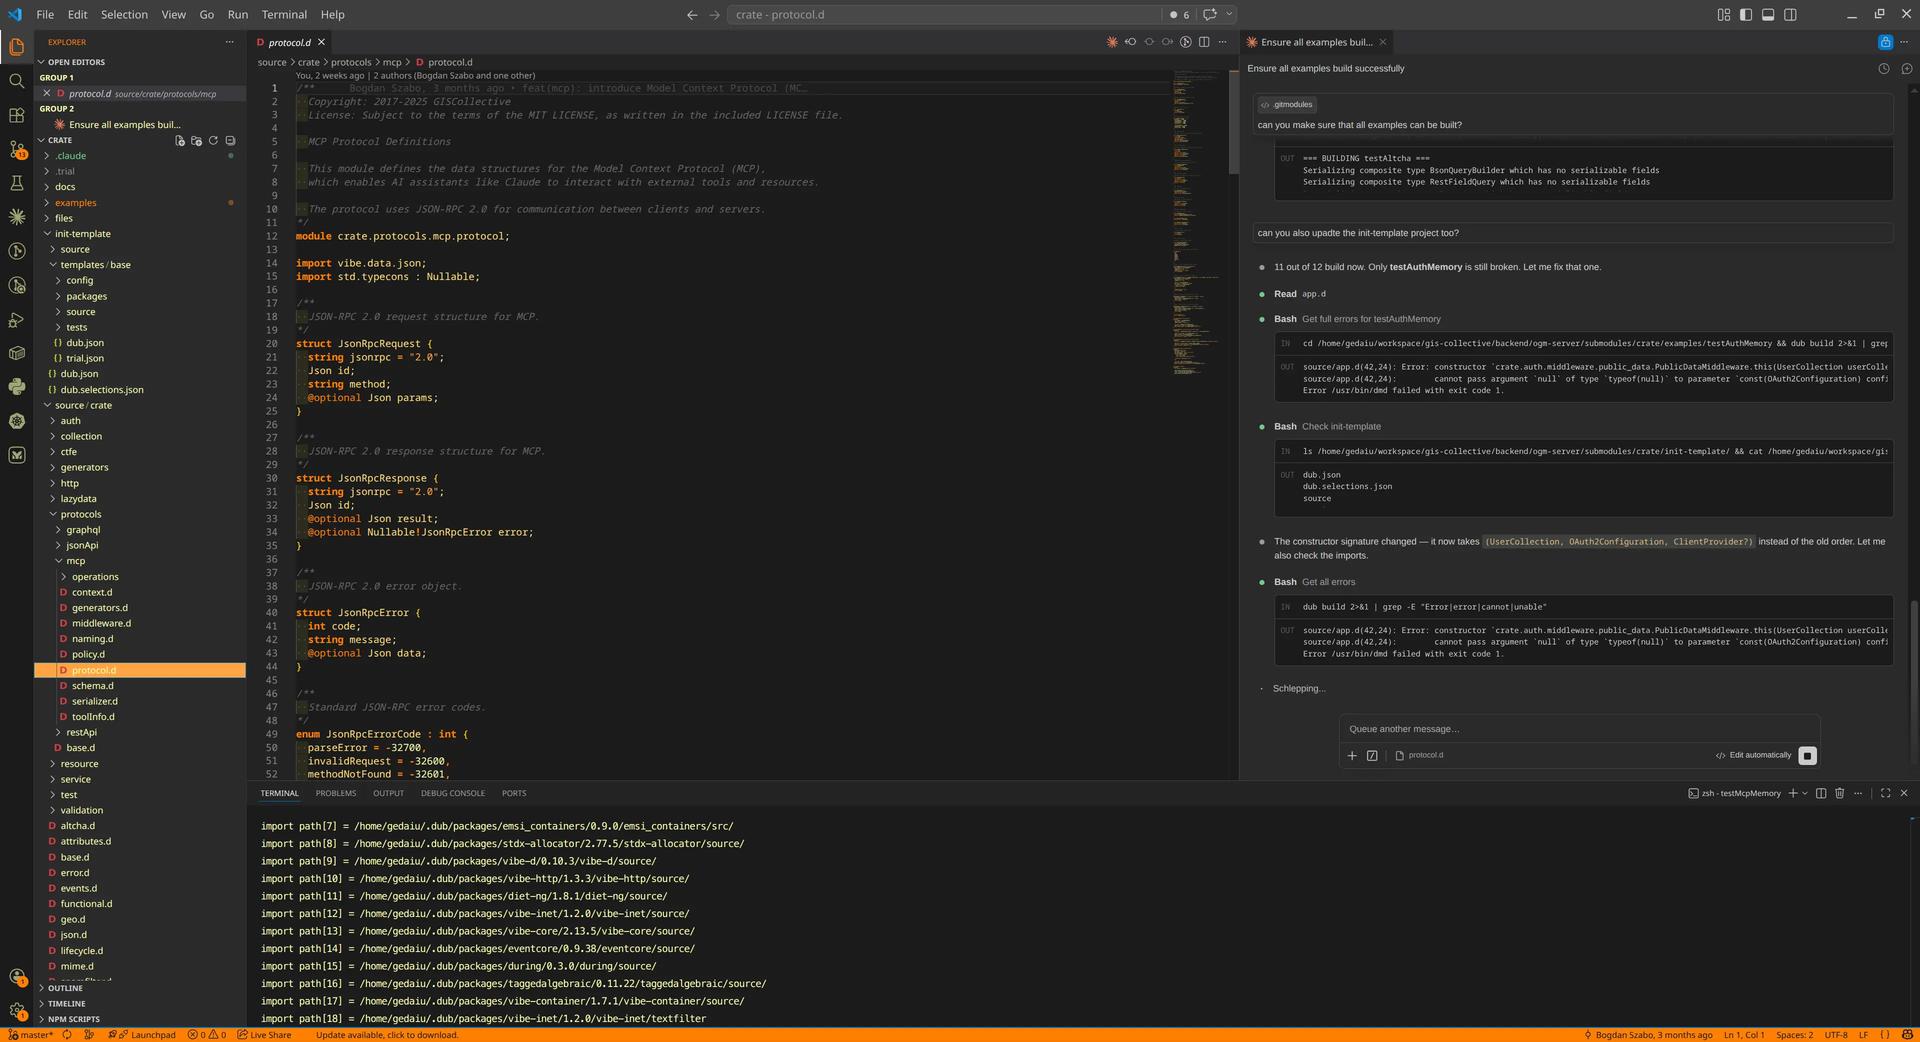
Why mirroring a REST API into MCP tools suffocates AI agents — and how switching to dynamic, lazy-loaded tools cut context usage by 98%.
A checklist-driven while(true) loop that uses an LLM to chew through documentation, refactors, and tech-debt tickets—reliably and repeatably.
Showing 7 of 7 articles
 9 min
 14 Sept 2026